Maxun
The free alternative toScrapingBee
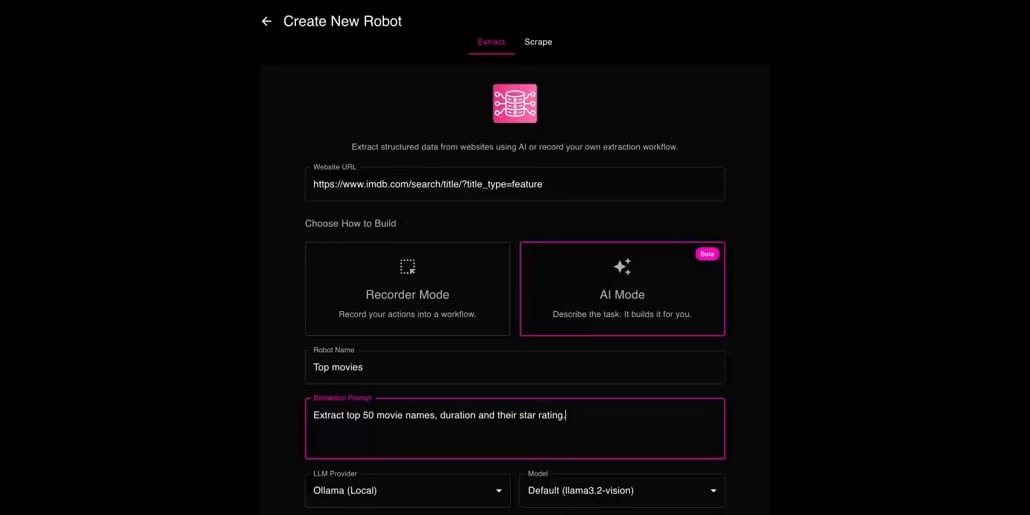
Maxun is the open source alternative to ScrapingBee: it turns any website into clean data, without code. You build a robot by clicking on what you want to collect, and it replays the path on every run, next pages included. Or you describe it in one sentence and AI builds it, with Claude, ChatGPT or a local model through Ollama. Run it on a schedule, even behind a login, or call it as your own API. Results go out as CSV, to Google Sheets, Airtable or a webhook. It installs with Docker Compose: plan for at least 4 GB of free memory and keep it updated. The limit: proxy rotation and captcha solving are reserved for their cloud. On sites that block robots, you need your own proxies, which are paid.
Versus ScrapingBee: the match
Price
Maxun
€0 on your machine
ScrapingBee
€17/month (Hobby)
Pages a month
Maxun
Unlimited
ScrapingBee
About 15,000 with JavaScript
Protected sites (proxies, captchas)
Maxun
Your own proxies, paid
ScrapingBee
Included
| VS | Maxun | ScrapingBee ↗ |
|---|---|---|
| Price | €0 on your machine | €17/month (Hobby) |
| Pages a month | Unlimited | About 15,000 with JavaScript |
| Protected sites (proxies, captchas) | Your own proxies, paid | Included |
| No code | Robots built by clicking or described in one sentence | An API to call from your code |
| AI extraction | Claude, ChatGPT or a free local model | 5 extra credits per page |
| Monitoring and scheduled runs | Included | Up to you to schedule |
| What you need | Docker and 4 GB of memory | An API key |
How to install it (even from zero)
Five Docker services, including a browser, on your computer or your server. The prompt installs the free version from the official repo, connects an AI model for the describe mode and builds your first robot with you.
- 1
Paste this prompt into Claude (Code or Desktop)
It installs Maxun from the official repo, secures the configuration, connects the AI and schedules your first robot:
Installe Maxun sur ma machine : c'est la plateforme open source qui remplace ScrapingBee pour extraire des données de sites web (dépôt GitHub getmaxun/maxun, site maxun.dev). Vérifie d'abord que Docker est installé et que la machine a au moins 4 Go de mémoire libres. Suis ensuite le guide Docker Compose de la documentation (docs.maxun.dev) : récupère le docker-compose.yml et le fichier d'exemple des variables d'environnement du dépôt, remplace toutes les valeurs d'exemple par des mots de passe et des clés secrètes solides, et lance l'ensemble. Si c'est sur un serveur, place l'interface derrière mon nom de domaine en HTTPS. Pour le mode IA, branche ma clé Anthropic, ou installe Ollama si je préfère un modèle local gratuit. Crée ensuite avec moi un premier robot sur un site public de mon choix, en mode enregistrement puis en mode IA, et montre-moi comment exporter en CSV, envoyer les résultats dans Google Sheets et programmer un passage chaque jour. Explique-moi aussi quoi faire si un site bloque le robot (proxies), et comment mettre Maxun à jour. Explique chaque étape simplement, je débute.

Review the GitHub repository and check whether it is safe to install given my machine and my infrastructure. Ask me as many questions as possible, using widgets, to clarify my request and be as precise as you can.
- 2
Start with a public site
Test on a site with no anti robot protection: that is where the free version does everything. For a site that blocks you, you will need to plug proxies into the settings.
- 3
Respect the site's rules
Read the terms of use, space out your runs so you do not overload the site, and mind the GDPR as soon as you collect personal data.
 Paste this prompt into Claude (Code or Desktop)
What you actually do with it
Watch your competitors' prices
A robot checks a shop's prices every day and sends the results to Google Sheets: your price watch runs by itself.
Feed Claude clean pages
Maxun turns a page or a whole site into Markdown: Claude reads clean text instead of code full of menus and ads.
Grab a whole list in one click
Listings, job offers, product pages: you click on one example, Maxun collects the whole list, following pages included.
Project health, at a glance
Before installing an open-source tool, one question matters: is the project alive? These scores are computed from public GitHub data. They are not made up.
80/100
ExcellentVery active, well-maintained project: go ahead with confidence.
- Activity
- 100
Is the code moving? (commits in the last 30 days)
- Maintenance
- 100
How fresh is the latest update? Fresher is better.
- Community
- 80
Stars and contributors: people around means help and fixes.
- Maturity
- 90
Project age. Old enough to be solid, still alive.
- Momentum
- 31
Current pace versus its usual pace: speeding up or dozing off?
The repo in numbers
- GitHub stars
- 18.3k
- Forks
- 1.6k
- Contributors
- 55
- Commits
- 7.8k
- Project age
- 3.1 yrs
- Last commit
- 4 d ago
- Size
- 8 MB
- License
- AGPL-3.0
Built with
- TypeScript 93.4%
- JavaScript 6.4%
Scores computed automatically from the GitHub API (last-30-days activity, update freshness, community size, project age). Refreshed daily.
Loucash’s take
7/10
Maxun has what ScrapingBee does not: you build your robots without code, by clicking on the page or describing what you want in one sentence. For collecting data from public sites, prices, listings, catalogues, it is free with no page limit. What I like: the AI mode with a local model through Ollama, so no cost per page, and the MCP server that lets Claude run the robots for me. Why 7 and not more: the free version lacks what ScrapingBee charges for, rotating proxies and captcha solving. On a site that blocks robots, you will have to pay for proxies or move to their cloud. The project is still at version 0.0.47, with a flaw fixed in June 2026, so updates are a must. And you need Docker and a machine with some memory.
It’s for you if: You want to collect data from public sites on a regular basis (prices, listings, catalogues, content for Claude) without coding or paying per page. If you need to extract heavily protected sites at scale, ScrapingBee or a proxy service will still be needed.
Also worth a look in the library
OpenSEO
Data & analytics€134/moThe open source SEO tool that does the job of Semrush and Ahrefs: keyword research, backlinks, rank tracking, site audit, visibility in AI answers. The software is free and self-hosted; the SEO data is pay as you go, a few cents per request, no subscription.
View details →
Casdoor
Data & analytics€31/moThe open source sign in server that replaces Auth0: a login page in your colours, sign in with Google and about a hundred others, two factor authentication, enterprise SSO. Your user accounts stay on your server, with no bill that grows with them.
View details →
PocketBase
Data & analytics€22/moA complete backend in a single file: SQLite database, user accounts, files, realtime and an admin dashboard. You run it on your server and get the equivalent of Supabase or Firebase, with no subscription.
View details →
One email a week that saves you money
Every Tuesday: the open source alternatives that just entered the library, what they replace and what they save you. One email, nothing more.
Free. One email on Tuesdays. Unsubscribe in one click. Your data


Join the Tuesday readers